
A/B testing for AI models, prompts and flows
Find out which AI model wins on your data
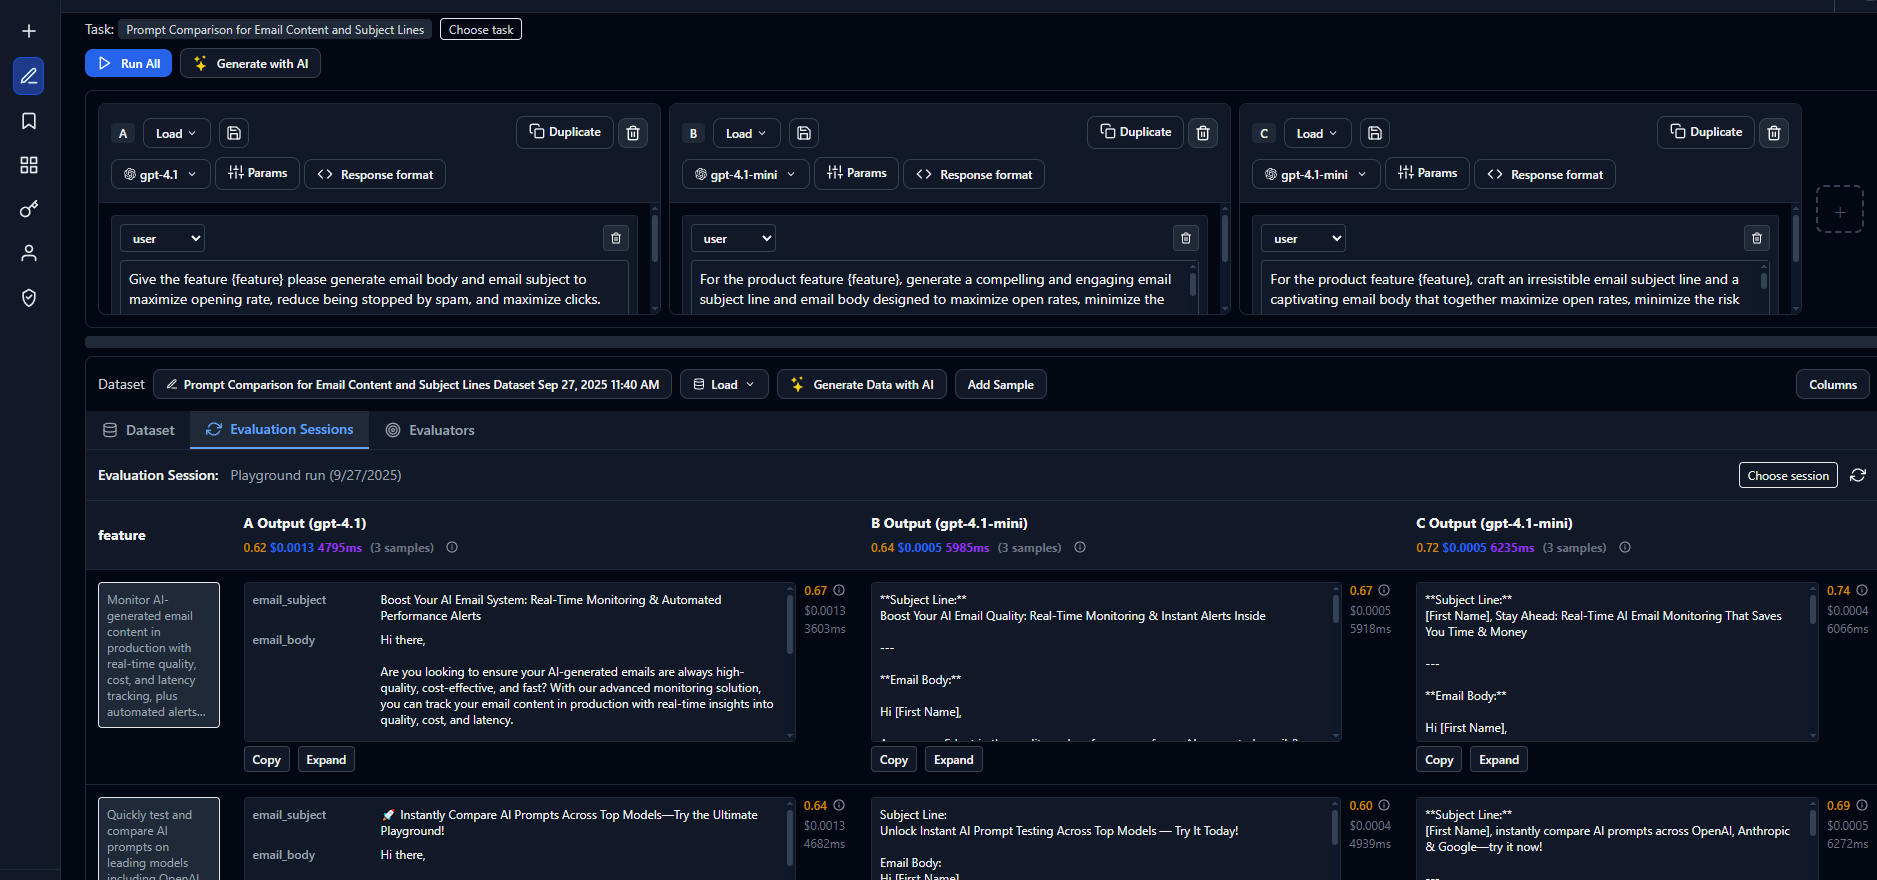
Run the same prompt or flow on several AI models, score every output with blind AI judges, and compare quality, cost and speed side by side. Then deploy the winner as an API.
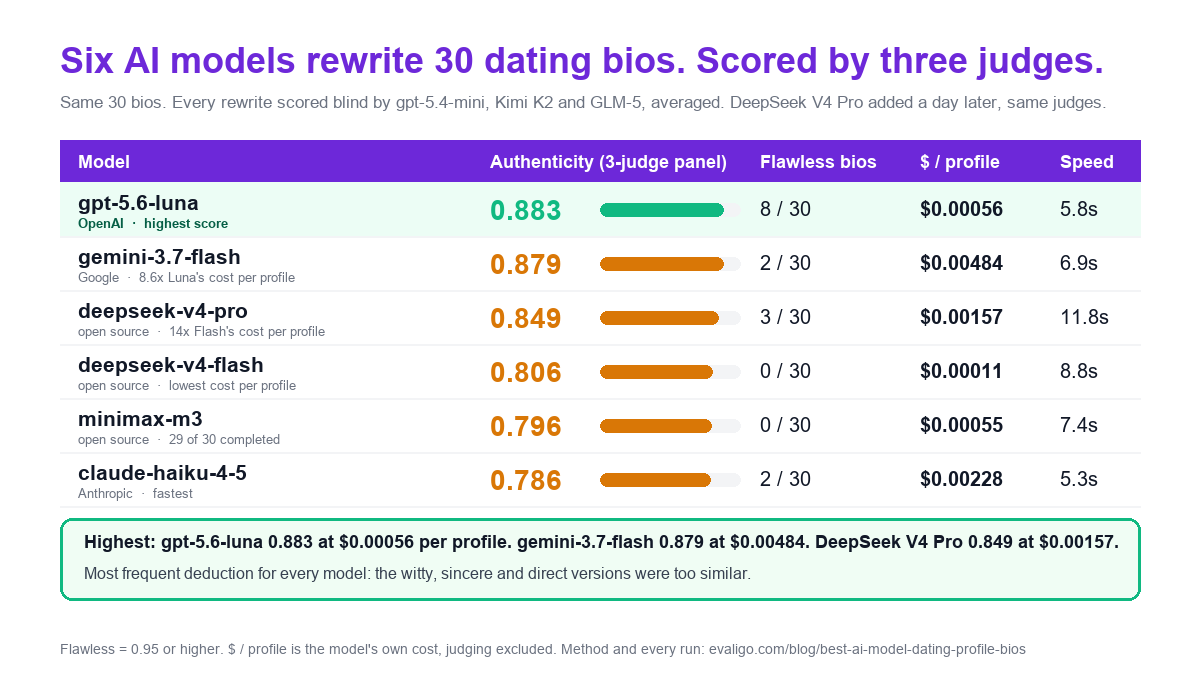
A real Evaligo experiment: six models, the same 30 inputs, three blind judges. Read the full write-up.
Compare models, prompts and flows on the same inputs
Any model as a variant, including open source
Pick the models you want to compare: OpenAI, Google, Anthropic, and open-source models such as DeepSeek, MiniMax, Kimi and Qwen through one OpenRouter key. Each variant runs the same flow on the same inputs; only the model, prompt or reasoning setting changes.
View DocsCompare models free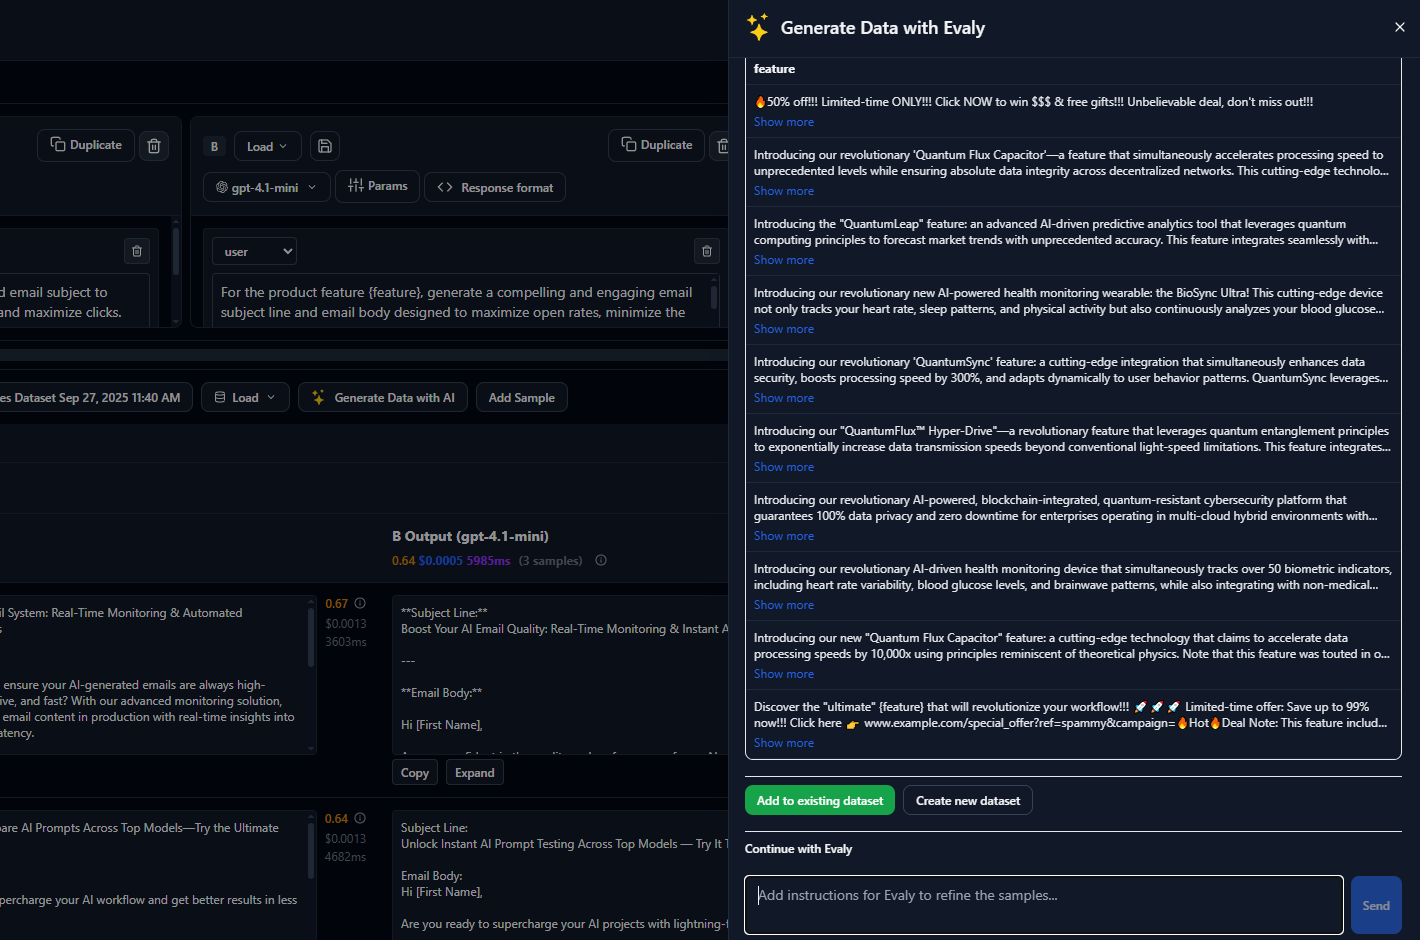
Test on your own data, or generate it
Run every variant over a dataset of real inputs. If you have none yet, Evaligo generates a realistic test set from a one-line description, so a 30-sample comparison is ready in minutes.
View DocsCreate a test setJudge every output blind
Rubrics, not vibes
Write the criteria once: what a good output must do, and what costs points. AI judges score every output against the rubric without knowing which variant produced it, and record a one-line reason per score.
View DocsWrite your first rubric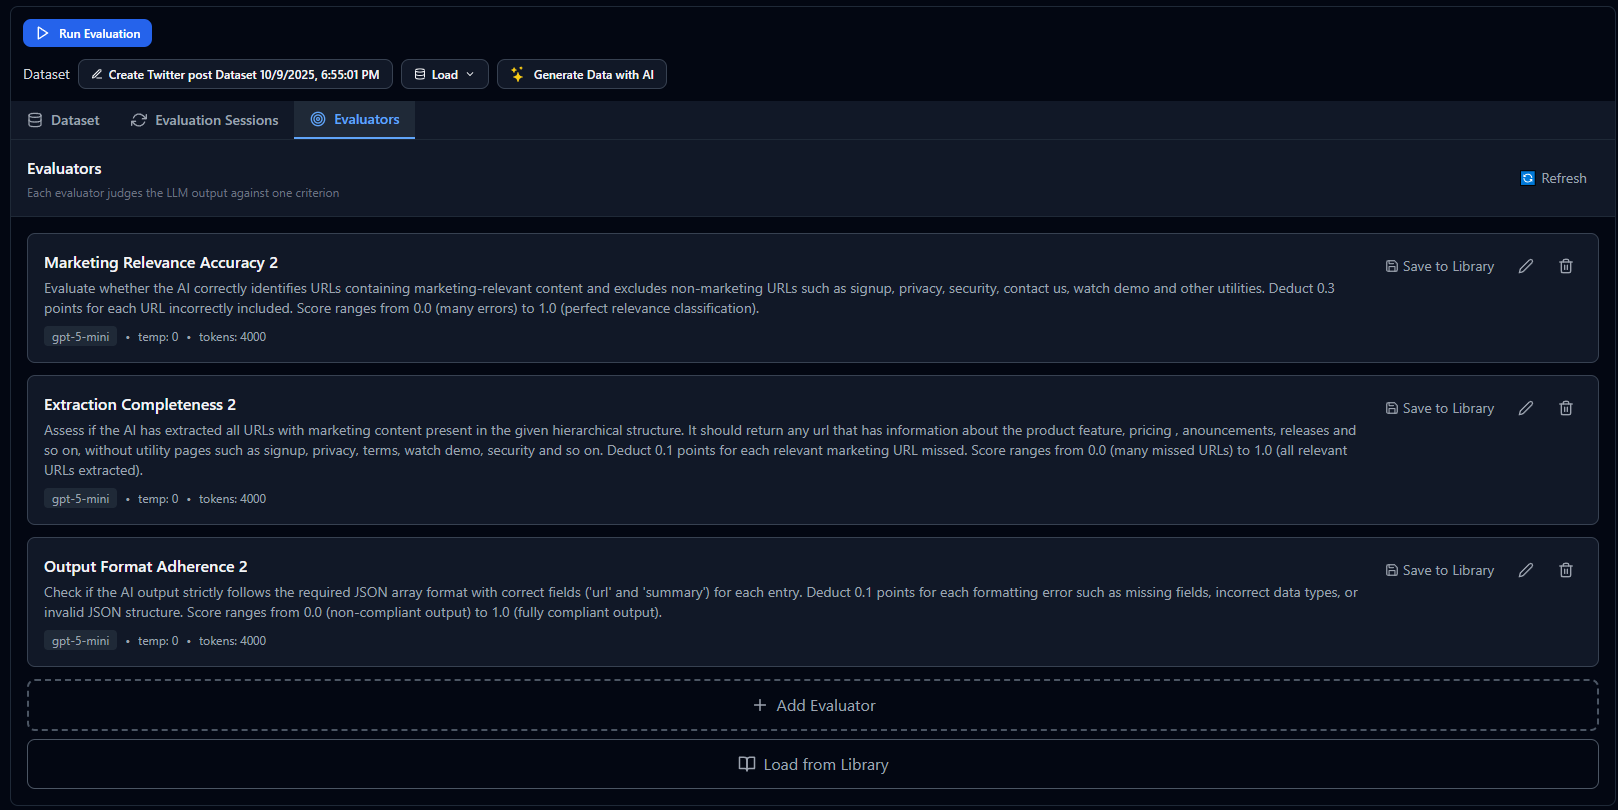
Judge panels from several vendors
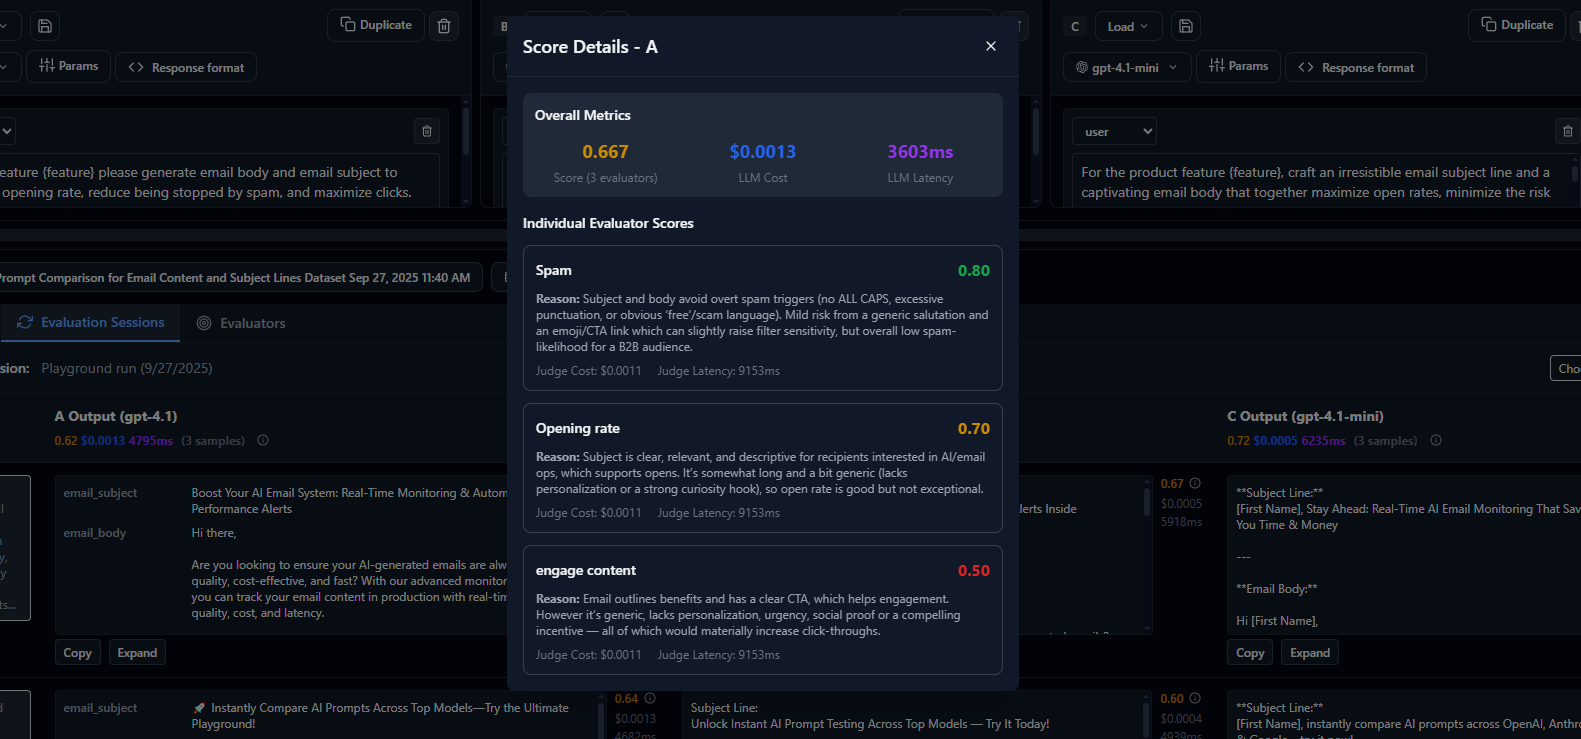
Use one judge model or a panel of three from different vendors, averaged. Per-judge scores stay visible, so you can see where the judges agree and where they do not.
View DocsSet up a judge panelRepeat runs, on purpose
Model output and judging both vary between runs. Re-run an experiment with one click and compare runs side by side before you decide.
View DocsRun an experimentRead the scoreboard, ship the winner
Quality, cost and speed per output
Every experiment ends in one table: score, flawless outputs, cost per output and latency for each variant, with a score distribution per sample. Export it as a PDF report.
View DocsPromote the winning variant
Make the winning model, prompt or flow the live version with one click. The flow keeps its inputs, outputs and API endpoint.
View DocsDeploy as a production API
Any flow deploys as a REST API with authentication, documentation and code examples. Batch processing and monitoring are built in.
View DocsBuilt on a visual flow builder
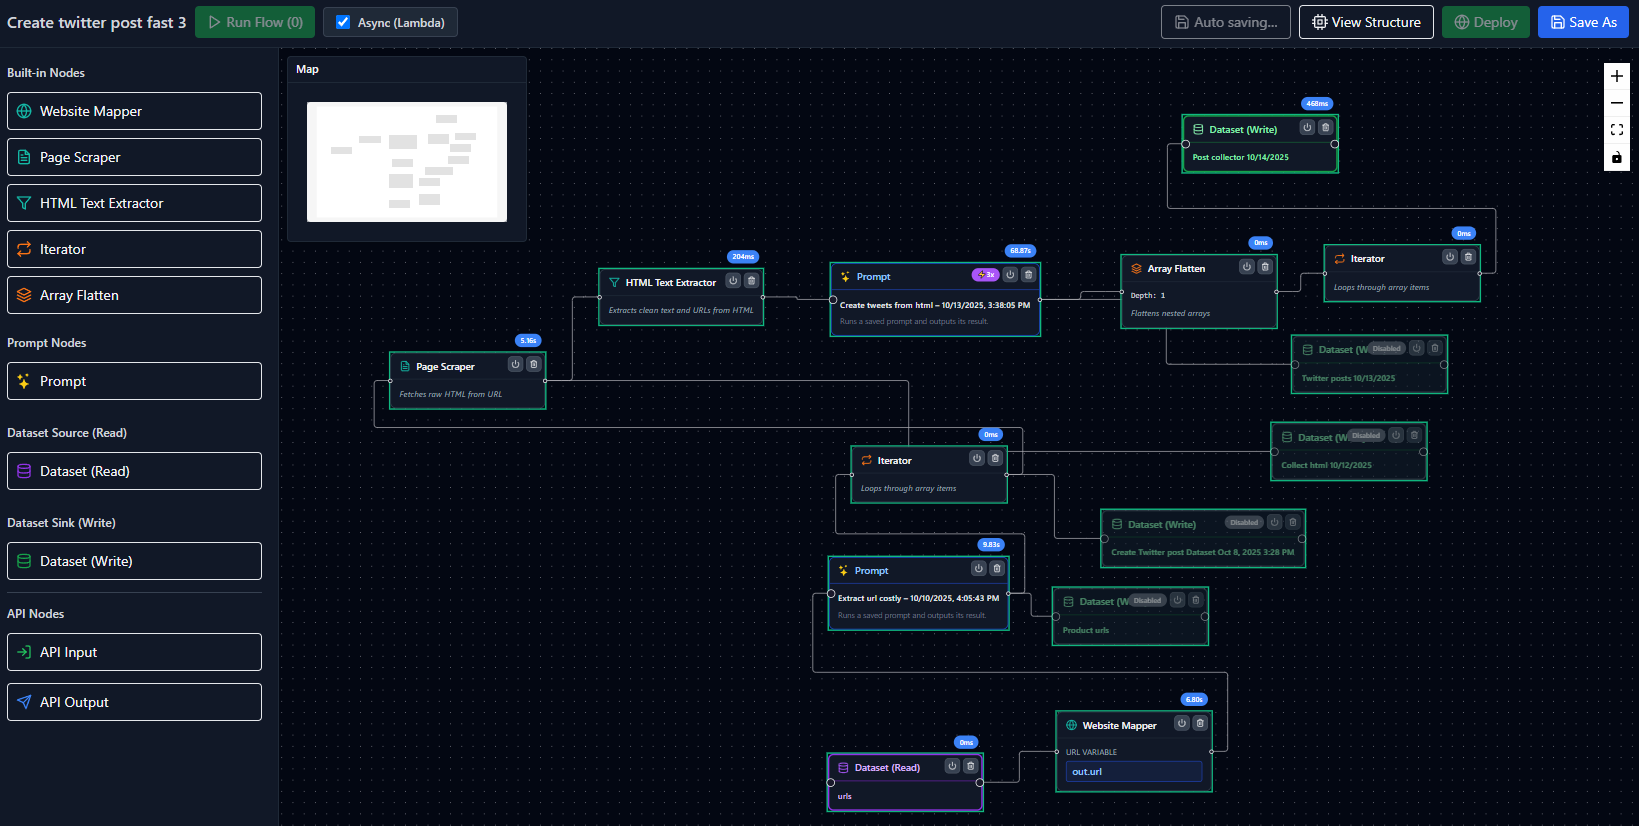
Describe the flow in one sentence and Evaligo builds it: prompts, web scraping, data extraction, tools and agents as connected nodes. Edit visually or by instruction.
View DocsBenchmarks we published, run on Evaligo
Every number below comes from an experiment you can reproduce: the same flow, the same inputs, blind judges, cost and speed per output.
Open source vs closed on writing
Six models rewrite 30 dating bios; three blind judges. gpt-5.6-luna 0.883, gemini-3.7-flash 0.879, DeepSeek V4 Pro 0.849.
Read the scoreboardModel versions, not just vendors
Salary negotiation coach on 30 offers. Gemini Flash 3.5 scored 0.68; the 3.7 release scored 0.75 at 3.5x lower cost, with no prompt change.
Read the scoreboardAgent architectures head to head
One agent, an assembly line, or agent plus editor: the same task built three ways, eight model mixes, a 14-criteria judge panel.
Read the scoreboardSimple, Transparent Pricing
Start free, scale as you grow. All plans include our core features with no hidden fees or surprises.
Free
Perfect for exploring and personal projects.
- 500 credits/month
- Visual workflow builder
- Web scraping & browser automation
- 20+ AI models (GPT-4, Claude, Gemini)
- All integrations (GitHub, Bitbucket, etc.)
- Deploy as API endpoints
- One-time scheduled runs
- Bring your own API keys (unlimited)
Pro
For power users and production workflows.
- 10,000 credits/month
- Buy more credits when you need them
- Recurring schedules (hourly, daily, weekly)
- 10 concurrent API executions
- Priority email support
Credits are used for AI model calls with platform API keys. Use your own API keys for unlimited usage on any plan.
From question to scoreboard in an afternoon
Build the flow, test it across models on your data, and ship the version that scores best. The six-model benchmark on this page cost $3.18 to run.
Build
Describe the flow in one sentence, or paste the prompt you already use. Evaligo builds the flow as connected nodes; edit it visually or by instruction.
Test
Add variants: other models, other prompts, other reasoning settings. Run them all on the same dataset. Blind AI judges score every output against your rubric.
Ship
Read the scoreboard: quality, cost per output and speed for every variant. Promote the winner and deploy it as a production API with one click.
Trusted by teams at:
Stop guessing which model to use
Run your prompt or flow on several models, let blind judges score the outputs, and pick the winner on quality, cost and speed.
Forever free plan • 500 free credits monthly • No credit card required • Cancel anytime
Latest benchmarks and guides
Explore our newest tutorials, use cases, and documentation to get the most out of Evaligo
Six AI models rewrite 30 dating bios
Open source vs closed, scored by three blind judges: gpt-5.6-luna 0.883, gemini-3.7-flash 0.879, DeepSeek V4 Pro 0.849
Which AI negotiates your salary best?
Three models on 30 job offers; the Gemini version upgrade moved the ranking without a prompt change
One agent, an assembly line, or agent + editor?
The same AI agent built three ways, eight model mixes, a 14-criteria judge panel
Best AI Workflow Builders 2026
Comprehensive comparison of the top 10 AI workflow automation platforms
Evaligo vs n8n
See how Evaligo compares to n8n for AI-native workflow automation
Website to Twitter Posts
Automate social media content from any website with AI-powered workflows

Build an AI Logo Generator
Create stunning custom logos using AI image generation workflows

Marketing Automation
Drive faster growth with AI-powered marketing automation workflows
Compare All Tools
In-depth comparisons: Evaligo vs Zapier, Make.com, and other automation platforms